Taking the notepad apart
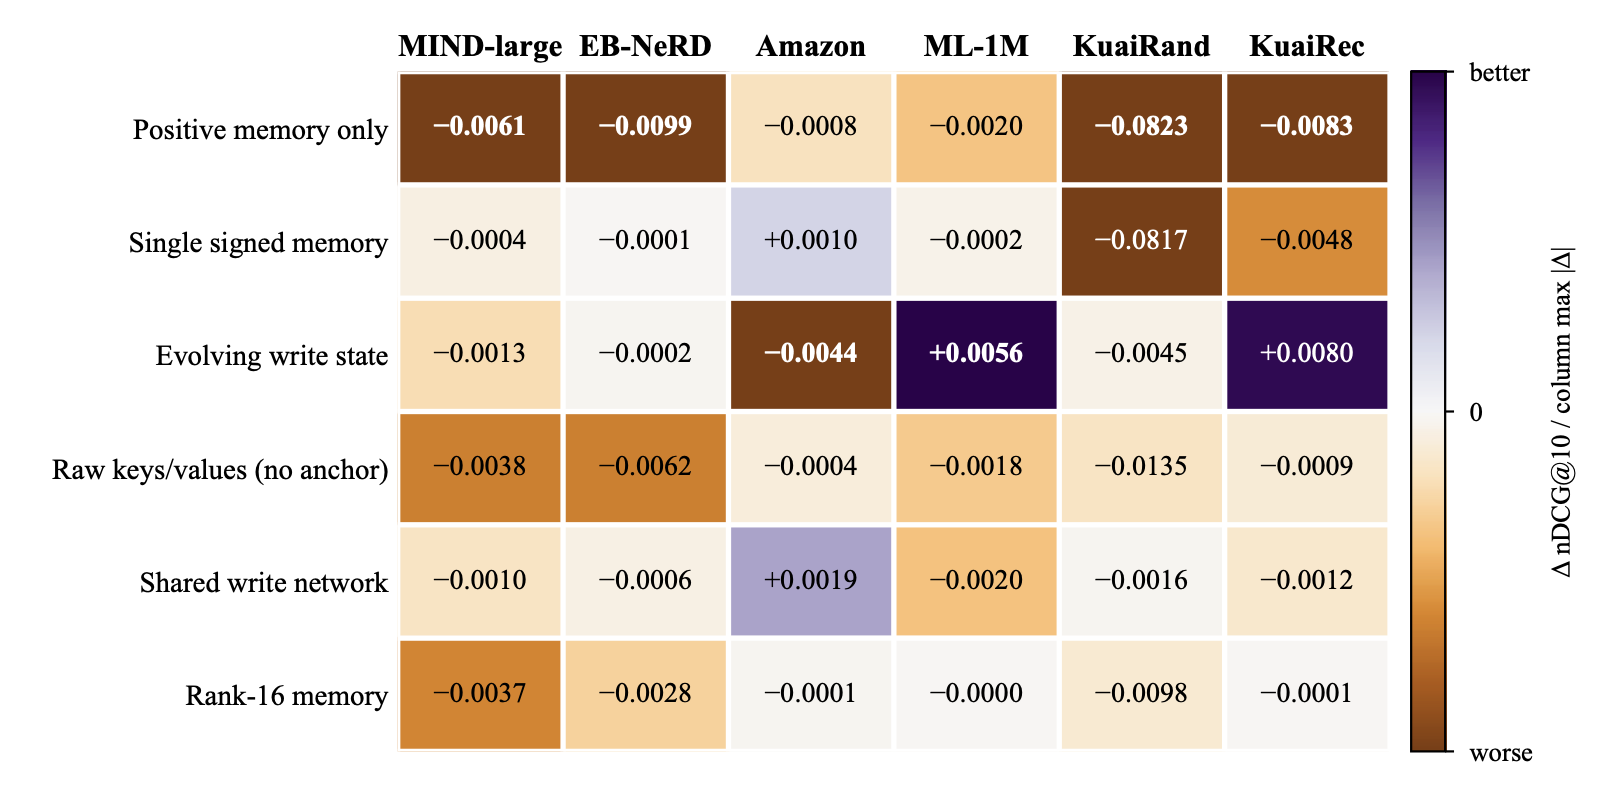
We removed or swapped one piece of the locked notepad model at a time — dislike memory, the separate pads for likes and dislikes, the fixed writing anchor, the anchor-based note format, the independent writer networks, and the full-size pad — and reran the exact main-table protocol each time: same data, splits, seeds and settings, with the untouched model as the baseline. Every bar below is a three-seed test mean.
The signed dual memory is the load-bearing part. Remove the dislike pad — or merge both signs into one pad — and KuaiRand, the dataset with real dislike buttons, drops by 0.082 nDCG@10; the news datasets lose a smaller but consistent amount without dislikes. Every other change costs at most ~0.006 anywhere: the moving write state is a wash, the writer architecture barely matters, and the rank-16 compressed pad matches the full pad on all six datasets — the notepad can be shrunk but its two signed halves cannot be merged.
How much each change costs · Δ nDCG@10 vs the full notepad
Bars hang below the line when a change hurts and rise above it when it helps. Each dataset is scaled to its own largest change — printed under every group — because KuaiRand's −0.082 would otherwise flatten the five datasets whose changes are ten times smaller. Compare bar heights within a group, and read the printed scale when comparing across groups. Hover any bar for its exact delta.
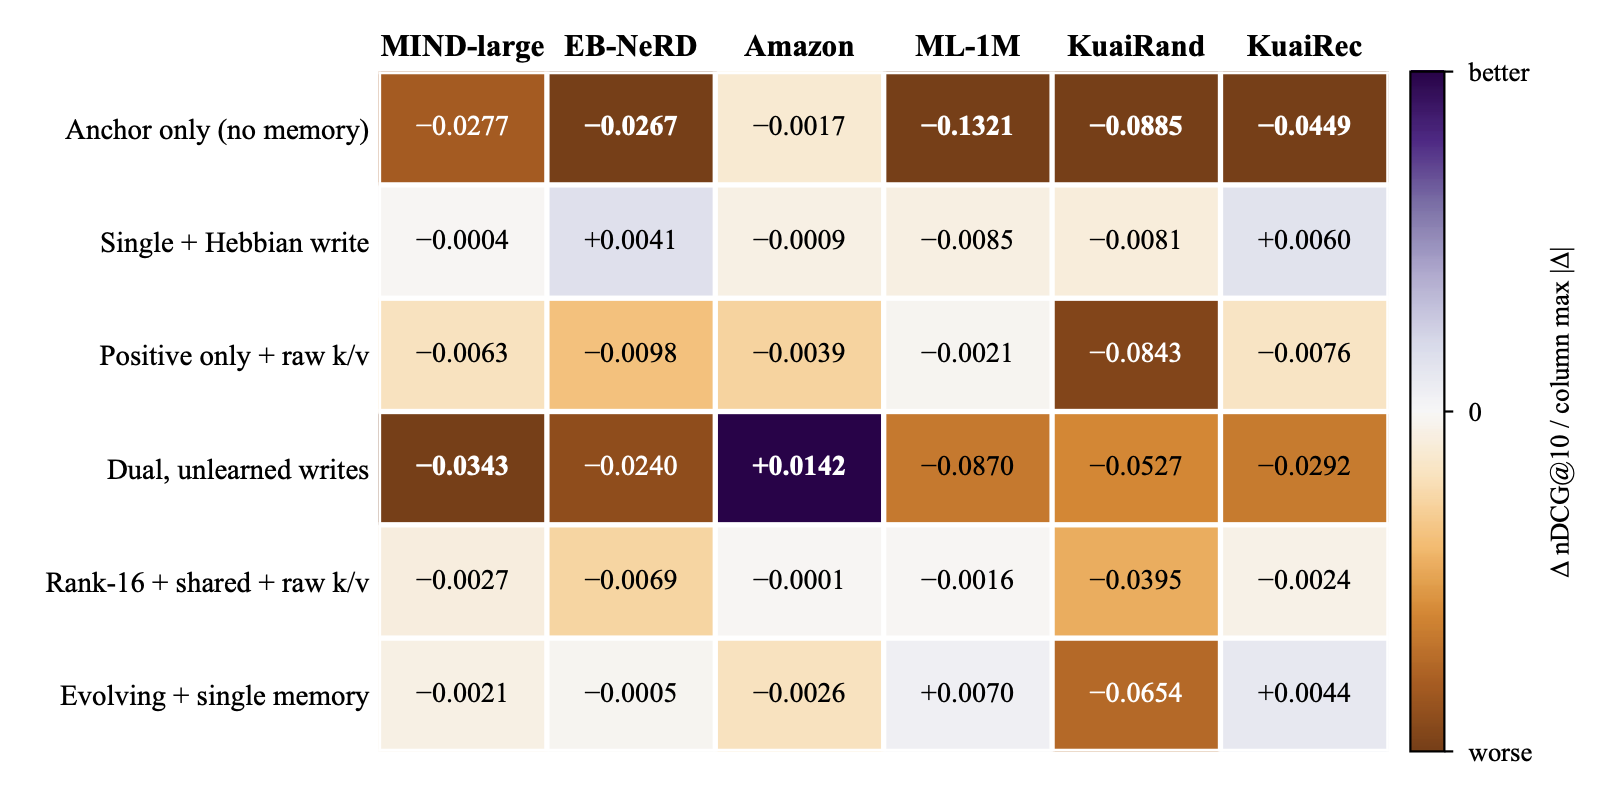
Combination ablations · several pieces changed at once
Removing one piece at a time understates the memory: the pieces cover for each other. These runs change several at once (same protocol, three seeds, per-dataset scaling as above). The headline: on MovieLens-1M no single removal cost more than 0.002, yet removing the whole memory costs 0.132 — the components are individually replaceable but jointly essential. A crude single Hebbian pad recovers almost all of that value everywhere except KuaiRand, whose real dislike signals need the full signed machinery; and on Amazon the memory adds almost nothing at all.
| Combination removed / changed | MIND-large | EB-NeRD | Amazon Video Games | MovieLens-1M | KuaiRand-Pure (IDs) | KuaiRec |
|---|---|---|---|---|---|---|
| Anchor only — the whole memory removed | -0.028 | -0.027 | -0.002 | -0.132 | -0.089 | -0.045 |
| One crude pad — single memory, no delta rule | -0.000 | +0.004 | -0.001 | -0.009 | -0.008 | +0.006 |
| Likes only + notes without the anchor base | -0.006 | -0.010 | -0.004 | -0.002 | -0.084 | -0.008 |
| Dual pads but nothing learned in the writes | -0.034 | -0.024 | +0.014 | -0.087 | -0.053 | -0.029 |
| Lean stack — rank-16 + shared writer + raw notes | -0.003 | -0.007 | -0.000 | -0.002 | -0.039 | -0.002 |
| Moving write state + one shared pad | -0.002 | -0.001 | -0.003 | +0.007 | -0.065 | +0.004 |
The same numbers as a table
Negative numbers mean the change hurt. Red marks a drop of 0.02 or more. Every variant reuses its dataset's already-selected learning rate, forgetting rate and dislike weight, so only the named component changes.
| Change to the notepad | MIND-large | EB-NeRD | Amazon Video Games | MovieLens-1M | KuaiRand-Pure (IDs) | KuaiRec |
|---|---|---|---|---|---|---|
| Likes only — no dislike memory | -0.006 | -0.010 | -0.001 | -0.002 | -0.082 | -0.008 |
| One shared pad for both signs | -0.000 | -0.000 | +0.001 | -0.000 | -0.082 | -0.005 |
| Notes written against a moving state | -0.001 | -0.000 | -0.004 | +0.006 | -0.004 | +0.008 |
| Notes built without the anchor base | -0.004 | -0.006 | -0.000 | -0.002 | -0.014 | -0.001 |
| One shared writer network | -0.001 | -0.001 | +0.002 | -0.002 | -0.002 | -0.001 |
| Rank-16 compressed pad | -0.004 | -0.003 | -0.000 | -0.000 | -0.010 | -0.000 |
MIND-large · nDCG@10 by variant
EB-NeRD · nDCG@10 by variant
Amazon Video Games · nDCG@10 by variant
MovieLens-1M · nDCG@10 by variant
KuaiRand-Pure (IDs) · nDCG@10 by variant
KuaiRec · nDCG@10 by variant
Fine print
Variants follow the list promised in the paper's appendix. "Full" is pinned bit-identical to the locked model by test and reproduced its main-table numbers live. The rank-16 pad stores at most 16 note-pairs per memory (the write window holds 20 events), so it is exact until capacity and matched the dense pad within 0.010 everywhere. KuaiRand uses learned ID vectors (it has no item text); all other datasets use the shared frozen content vectors.
Paper figures
Publication versions of this page's charts, as PDF. Each series or cell is encoded twice (colour plus pattern, marker or printed value), so they read in greyscale and under colour-vision deficiency. Click a preview to open the PDF.